W-03 · Case study
ShieldPay
Built by Team Sentinel for Squad Hackathon 3.0 (May 2026), where it placed in the top 50 of 600 teams. The interesting decision wasn't the model; it was refusing to stop at a number.
- Hackathon prototype — runs locally on demo data; not used by real merchants
- Four people: API, ML, frontend and integration/agent
- squad/, agent/, rag/, network/, ml/retrain.py, synthetic data
- 19 integration tests (pytest + httpx)
- Python · FastAPI · scikit-learn · XGBoost · Groq · Llama 3.3 70B · ChromaDB · React
Thesis
A risk score is not a decision. It needs reasons, a fallback and a way to be corrected.
§ 01
The problem
Squad merchants receive a webhook for every settled payment, but nothing that helps them judge it: no scoring, no investigation, no way to act on a suspicious pattern or learn from a confirmed one.
§ 02
How the idea changed
The first proposal was a single Isolation Forest over webhook payloads. It produced a number — and a merchant can't do much with 0.73. The design shifted four times during the hackathon.
- Investigation over scoring: an agent calls analysis tools and returns a verdict with written reasoning.
- Local context: a small retrieval corpus of twelve documents on Nigerian fraud patterns, queried before each agent call.
- Reliability: a deterministic orchestrator that uses the same tools, so an LLM outage never disables the product.
- Shared memory: device fingerprints confirmed as fraud at one merchant are checked for every other merchant.
§ 03
The governing decision
ShieldPay sits behind the webhook, outside the payment path. Scoring happens after settlement, asynchronously, so it adds no latency to checkout — and it can be dropped in behind any merchant without touching their flow.
§ 04
The system
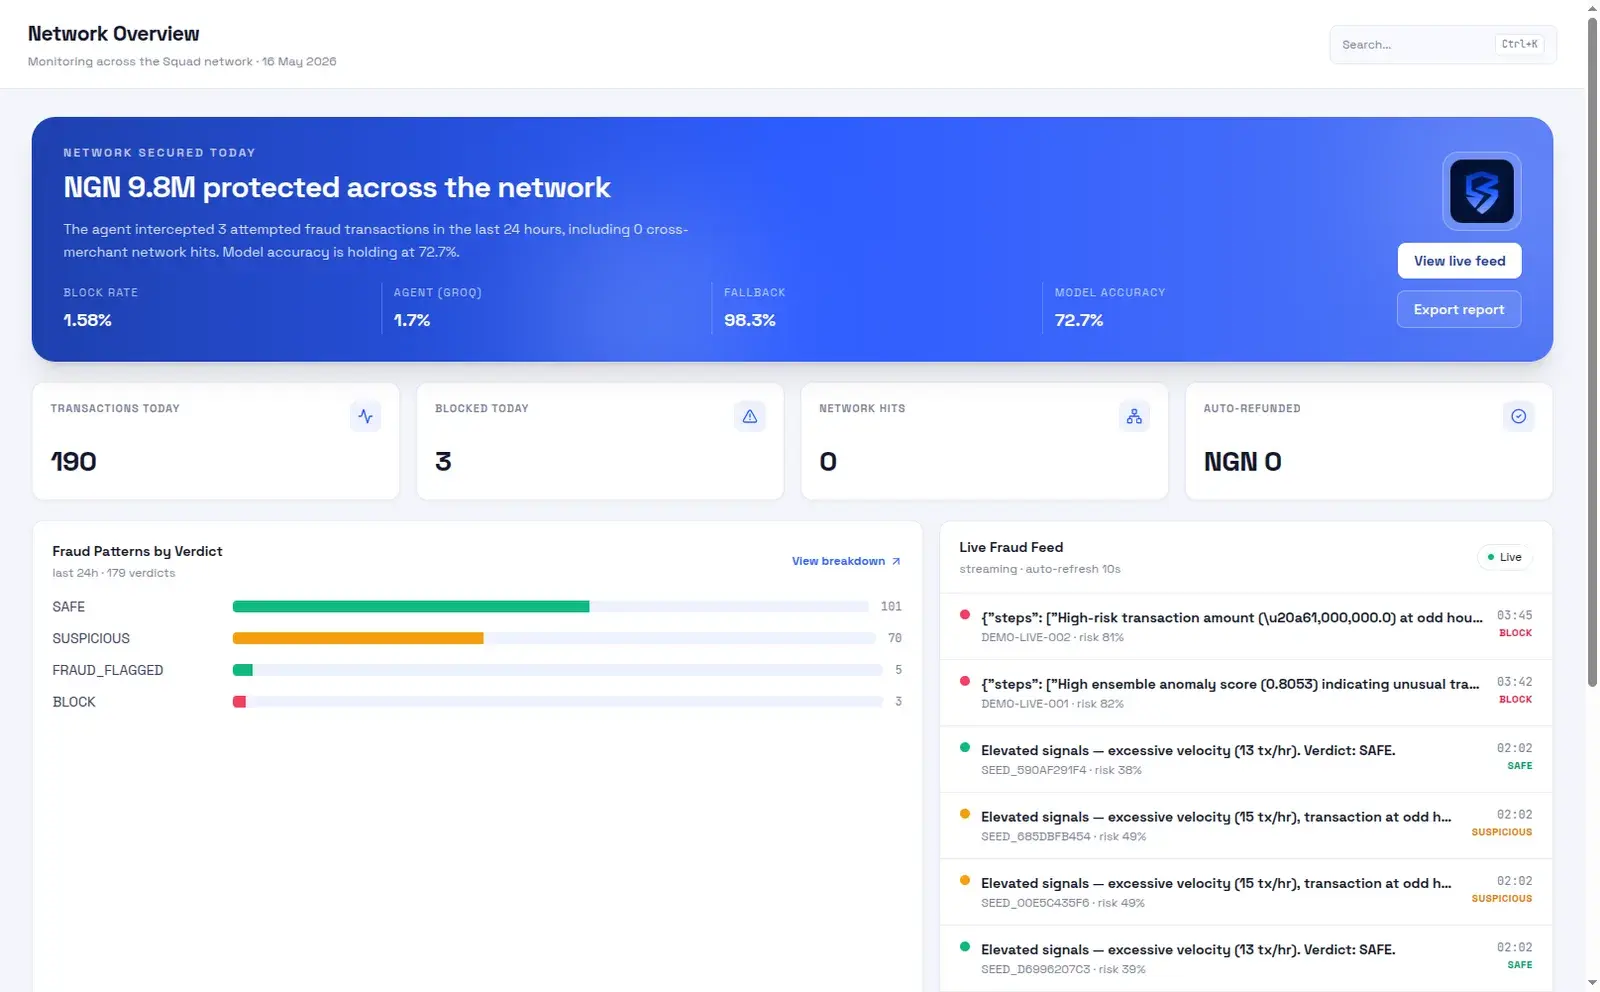
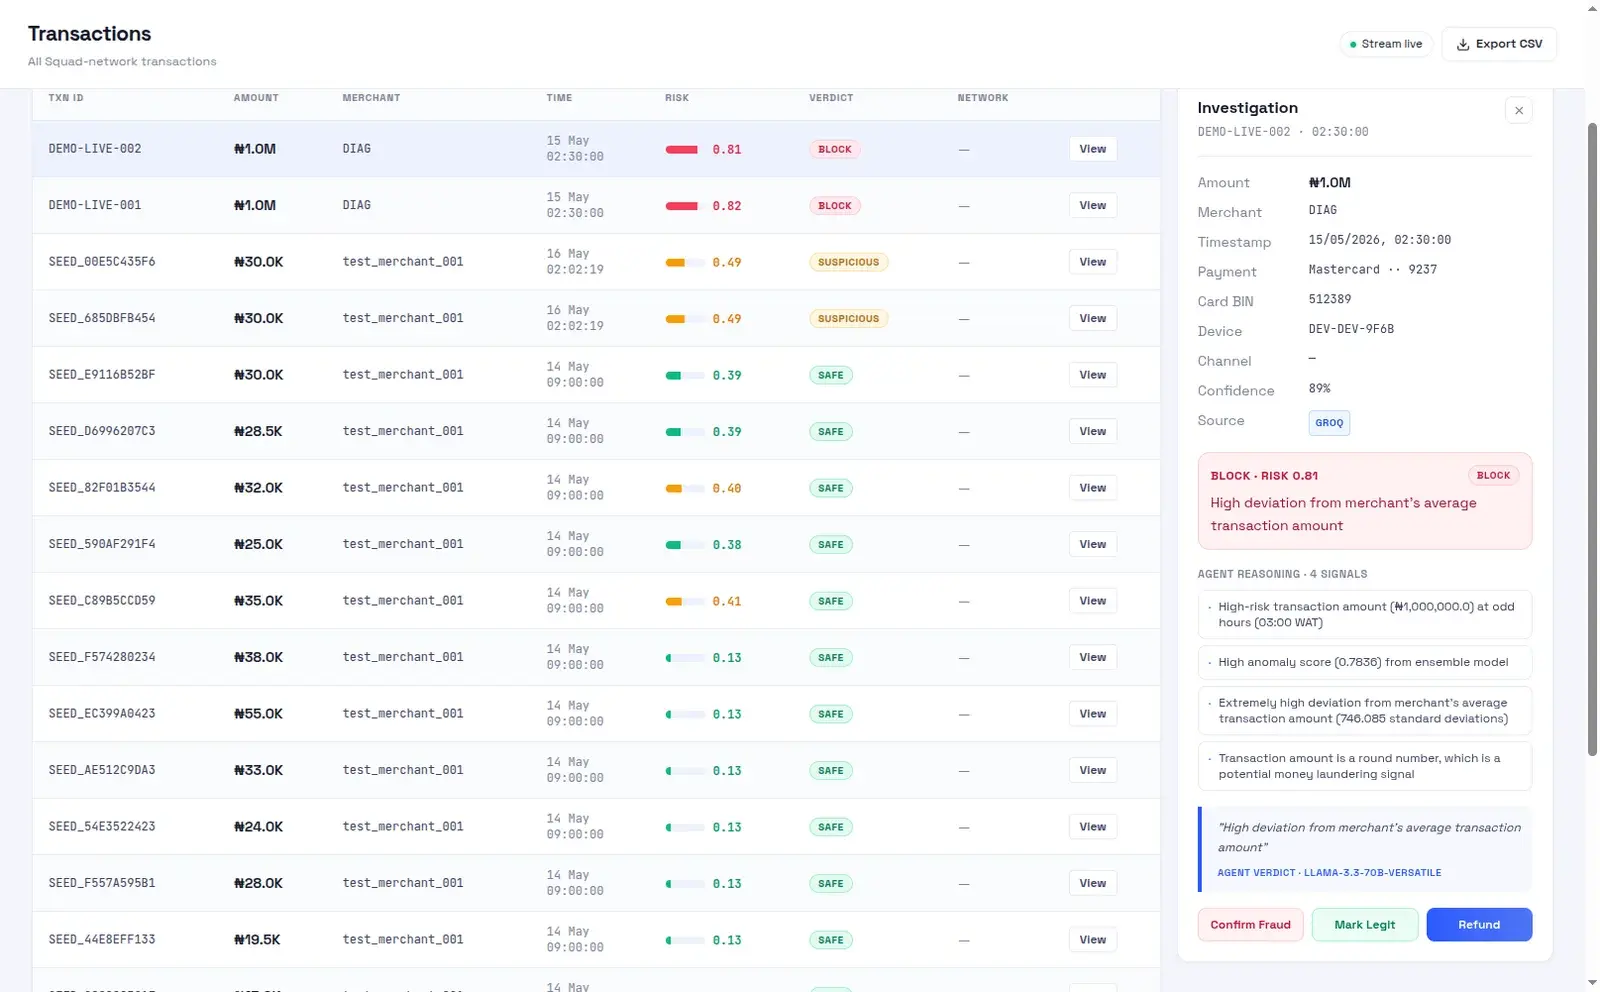
Every webhook is verified with HMAC-SHA512, enriched through Squad's verify endpoint and checked against the fingerprint store. Three or more hits block immediately. Everything else goes to a dispatcher that gives the Groq-hosted agent five seconds; on timeout or error, the deterministic path runs instead. Both call the same four tools — velocity, anomaly score, amount deviation, merchant profile — and every verdict is tagged with the path that produced it.
Choose a scenario to follow a transaction through.
Diagram 01
From a webhook to a verdict
A ₦950,000 payment at 02:30 from a new device.
HMAC-SHA512 signature check. Invalid signatures are rejected with 401.
Every stage, in words
- 01Verify (squad/hmac.py) — HMAC-SHA512 signature check. Invalid signatures are rejected with 401.
- 02Enrich (Squad /transaction/verify) — Pull the full transaction from Squad, flatten it, convert kobo to naira, hash user identifiers.
- 03Fingerprints (network/fingerprints.py) — Check device and IP against fingerprints confirmed as fraud at any merchant.
- 04Dispatch (agent/dispatcher.py) — Give the LLM agent five seconds. On timeout, rate limit or connection error, run the deterministic orchestrator.
- 05Tools (agent/tools.py) — Velocity, anomaly score (IsolationForest + XGBoost over 7 features), amount deviation, merchant profile.
- 06Verdict (SAFE · SUSPICIOUS · BLOCK) — A verdict, a risk score, the signals used and written reasoning, tagged with its source.
- 07Act (dashboard · refund) — Verdicts land in the merchant dashboard. Risk above 0.92 triggers an automatic refund through Squad.
- 08Learn (ml/retrain.py) — Merchant labels queue a retrain; a candidate model deploys only if it passes a shadow test.
§ 05
Limits of the model
The models were trained on roughly ten thousand synthetic transactions with injected fraud patterns — there is no real fraud data behind them. The ensemble weights (40% IsolationForest, 60% XGBoost) and the verdict thresholds were set by hand. The agent's reasoning is an explanation of the signals it used, not evidence that a transaction is fraudulent. The dashboards in the screenshots run on seeded demo data.
Those limits are why retraining is gated: a candidate model is only deployed if it passes a shadow test against the current one, so a noisy batch of labels can't quietly make scoring worse.
§ 06
What broke, and what changed
Integration exposed real faults. Training and inference had been built on two different feature sets — the saved models expected raw webhook fields while the retraining script produced engineered features. The fix moved everything to engineered features and added an online function that computes them for a single live transaction from that user's history.
The retraining loop also had mismatched model filenames and table names that would have crashed it before it produced anything; those were fixed and the loop tested end to end.
§ 07
Current state
A complete hackathon build that runs with Docker Compose, with or without a Groq key. Taking it further would need multi-tenant auth, rate limiting and audit trails, streaming feature computation, and a retrieval corpus that grows from confirmed cases rather than twelve seed documents.